In June 2025, Sam Altman put OpenAI’s own number on it for the first time: the average ChatGPT query, he wrote, uses “about 0.34 watt-hours, about what an oven would use in a little over one second, or a high-efficiency lightbulb would use in a couple of minutes.” Google’s own accounting, published two months later, lands nearby: a median Gemini prompt costs 0.24 Wh. Both figures are honestly derived, and both answer a narrower question than the one most readers think they’re asking.
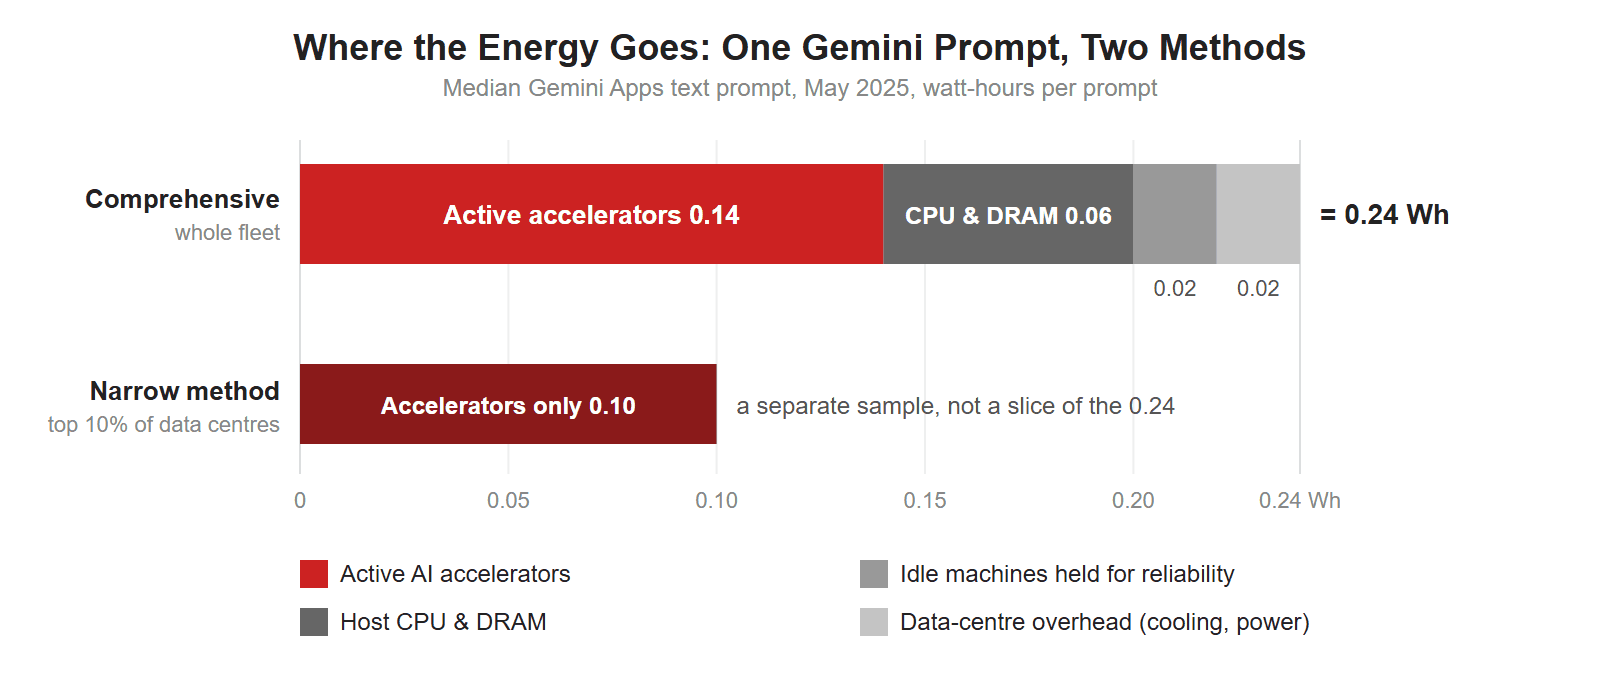
Google’s own August 2025 report prices its median Gemini text prompt at either 0.10 Wh or 0.24 Wh, a 2.4x gap that comes from method alone: what gets counted, and which machines are sampled. Almost nobody covering AI energy per query noticed. I read it as a mean-versus-tail problem wearing a press-release headline, and even the honest 0.24 Wh figure describes the typical prompt, which short chat replies dominate, at the moment usage is shifting toward reasoning and agentic workloads whose hidden token generation runs many times larger.
What the AI energy per query number actually measures
A watt-hour is a small, useful unit: run a 60-watt appliance for one hour and you’ve used 60 Wh, so a fraction of a watt-hour per query is tiny, and that smallness is part of why the recent numbers feel reassuring. Independent researchers and the two biggest chat operators have converged on roughly the same ballpark. Epoch AI puts a typical GPT-4o query at about 0.3 Wh, OpenAI cites 0.34 Wh, and Google’s comprehensive figure is 0.24 Wh.
That convergence looks like three separate parties checking each other’s maths and landing in the same place. Mostly, though, they agree about which question to answer. All three describe a typical text prompt: Epoch models a typical query with about 500 output tokens, Google reports the median Gemini Apps text prompt, and OpenAI gives an average without a published method. Typical prompts are dominated by short chat replies, the cheapest and most common request an AI system handles. None of them reports a reasoning chain, an agentic workflow or a multi-step task separately, and that gap is about to matter a great deal, given the grid constraints already reshaping how AI data centers get built.
The numbers used to be scarier. The old ~3 Wh per-query figure that circulated for years traces back to a 2023 estimate by researcher Alex de Vries, published in the journal Joule. Epoch AI’s 2025 re-estimate came out roughly ten times lower. Its most important reason is a more realistic count of output tokens for a typical answer: 500 rather than 2,000. It also assumes newer accelerators (H100 chips instead of A100) and about 100 billion active parameters for GPT-4o, which is most likely a mixture-of-experts model, against 175 billion for GPT-3.5. It’s a rigorous piece of reverse-engineering by an independent group.
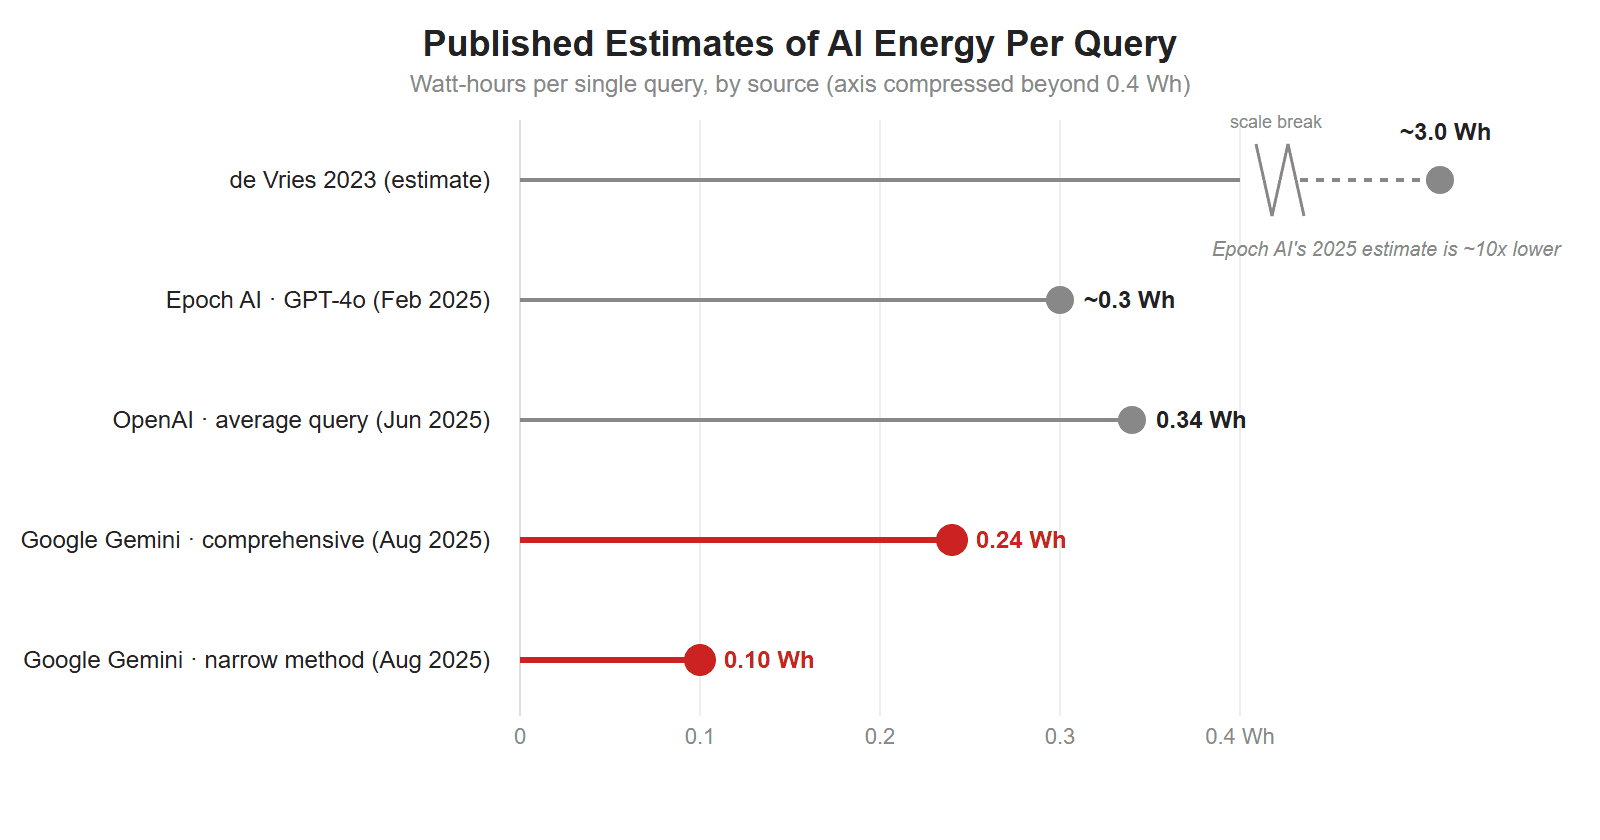
Chart it out and the pattern is obvious: four estimates from three sources cluster between 0.10 and 0.34 Wh, while the old 3 Wh figure sits off in its own compressed lane. That’s an order-of-magnitude correction, made fast, and it deserves credit. The numbers are honest. What interests me is what they all agree to leave out.
One prompt, two numbers: 0.10 Wh vs 0.24 Wh
Google’s August 2025 report gives two numbers for its median Gemini text prompt, and the gap between them is the whole story. The narrow figure, 0.10 Wh, follows the method most earlier studies used: it counts only the electricity the AI accelerator chips draw, and it samples prompts served in Google’s most efficient 10% of data centres, where utilisation is high, much like an optimised benchmark. The comprehensive figure, 0.24 Wh, averages across the whole fleet and adds everything a data center needs to serve that prompt reliably: idle machines held in reserve for failover and demand spikes, the host server’s CPU and memory, and data-center overhead like cooling and power distribution. It’s similar in spirit to PUE (power usage effectiveness), the multiplier engineers have used for years to describe how much extra energy a facility burns keeping its servers alive.
Google is unusually candid about which number to trust. In the same report, it calls the narrow accelerator-only method “an optimistic scenario at best” that “substantially underestimates the real operational footprint of AI,” and that admission is rarer than it should be. Most operators publish the smaller number and let readers assume it’s the whole picture. The reserve machines are also why data centers get built the way our earlier look at the AI power bottleneck describes: idle capacity is what makes reliable service possible at all.
The accounting debate doesn’t erase real progress, though. Over the twelve months from May 2024 to May 2025, Google says the median Gemini text prompt’s energy fell 33x and its total carbon footprint fell 44x, a rate of improvement that would be remarkable in any industry, let alone one this young. Google likes to compare 0.24 Wh to watching television for under nine seconds, and the water accounting moves in the same honest direction: 0.12 mL per prompt under the narrow boundary, 0.26 mL under the comprehensive one.
Get the next one by email
Power, cooling, chips and the rules that shape them. No spam, unsubscribe any time.
Why AI energy per query hides the real tail
Strip away the accounting debate and the underlying physics is simple: energy per query is roughly tokens generated multiplied by energy per token. Energy per token depends on how many floating-point operations (FLOPs) the model needs per token, how efficiently the accelerator converts watts into FLOPs, and how well the serving cluster batches requests. Batching runs many users’ prompts through the same GPU at once, which spreads its fixed power draw across more work and flatters the average.
A plain chat reply only generates the words you see. A reasoning model first produces a long hidden chain of intermediate tokens, scratch-work it never shows you, and that chain is often many times longer than the visible reply. Energy scales with total tokens generated, so a reasoning query can cost several times what a chat query does even when the two answers on screen are the same length.
Agentic workflows chain several such generations (a plan, a tool call, a reflection, another plan) into a single user request, as we’ve argued in looking at what actually drives AI agent memory costs. Published averages also leave out two things, which makes them systematically optimistic: the manufacturing energy embodied in the chips, and any amortized share of the original training run. So 0.24 Wh and 0.34 Wh are fair descriptions of the typical prompt, which short chat replies dominate. The case growing fastest is somewhere else.
The CERN rule: don’t design for the average event
Particle detectors taught me this before data centers did. You never characterize a detector by its average event, because the average is dominated by cheap, common, uninteresting collisions, and the physics, the trigger design and the bandwidth budget all live in the tail. A trigger system sized for the mean event rate would be swamped by the first real burst of interesting data.
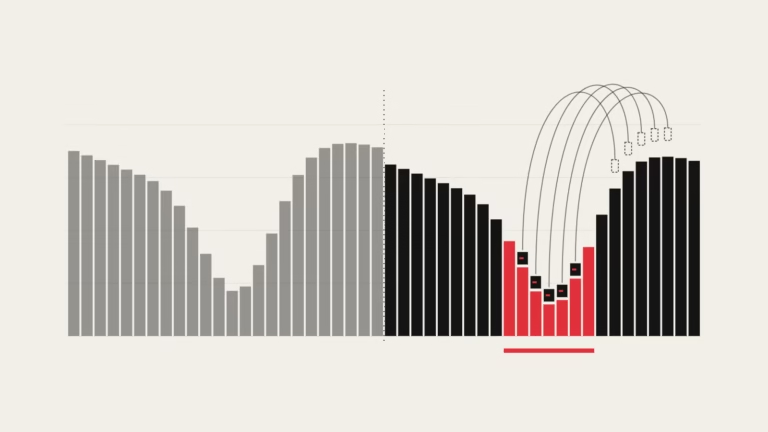
Quoting a median chat prompt as “the energy cost of AI” makes the same category error. It sizes the story to the mean while the growth, and the expense, sit in the tail of reasoning chains, agentic loops and video generation. Data-center capacity planning already works this way. That’s why serving architectures built around dense, high-utilization batching, like the wafer-scale approach to inference now changing how clusters get provisioned, will matter more to the real energy trajectory than any single per-query average.
⚡ PHOTON’S TAKE
I’ve seen this mistake twice now, first with detectors and now with data centers. You never size a trigger system to the average collision, and you shouldn’t size the AI-energy conversation to the average chat reply. Google deserves credit: it published the narrow number and the comprehensive number, and called the narrow one an underestimate outright. The efficiency gains are real, and 33x in a year is extraordinary. Quote 0.24 Wh for a reasoning model doing agentic work, though, and you’re mis-measuring exactly the tail that matters.
The efficiency gains are real. The question is still open
The published numbers aren’t fake, and the efficiency curve is remarkably steep: a 33x drop in a single year would make any hardware engineer’s decade. Google published its narrow figure, its comprehensive figure and an explicit warning about which one to trust, which is more transparency than this genre usually gets.
The fix is simpler than a methodology fight. Operators should report energy by workload class (short chat, reasoning, agentic, multimodal), the way they already report latency by percentile. I’d bet that breakdown becomes standard disclosure within two years, pushed by investors more than regulators, because the tail is where the real infrastructure spending is going and investors will want it modeled honestly.
Until then, when someone tells you an AI query costs a quarter of a watt-hour, ask them which query.
Cite this article
Major, A. (2026, September 14). AI Energy Per Query: Same Prompt, Two Different Numbers. ScienceShot. https://scienceshot.com/post/ai-energy-per-query
Major, Albert. “AI Energy Per Query: Same Prompt, Two Different Numbers.” ScienceShot, 14 Sept. 2026, scienceshot.com/post/ai-energy-per-query.
Major, Albert. “AI Energy Per Query: Same Prompt, Two Different Numbers.” ScienceShot, September 14, 2026. https://scienceshot.com/post/ai-energy-per-query.
@online{scienceshot-ai-energy-per-query-2026,
  author       = {Major, Albert},
  title        = {{AI Energy Per Query: Same Prompt, Two Different Numbers}},
  organization = {ScienceShot},
  date         = {2026-09-14},
  year         = {2026},
  url          = {https://scienceshot.com/post/ai-energy-per-query}
}
https://scienceshot.com/post/ai-energy-per-query
Get the weekly brief
Sourced analysis of data-centre engineering and regulation, every Monday. No spam, unsubscribe any time.